21st Lab · Benchmarks · Live Preferences · Hero
12 models designed heroes. Developers picked blind
AI-made hero sections went live on 21st's hero page. Signed-in members saw two at a time without knowing a model made them, and opening one counted as a pick
Designed and run by the 21st team
As of November 2, 2026, GPT-6 Astra leads with a 3.4% pick rate, then GPT-6.1 Sol at 3.3% and Grok 4.7 at 2.8%. Price doesn't buy the lead: GPT-6.1 Sol cost $1.50 for its run, Claude Fable 5.1 cost $15.96
Updated 11/02/2026How it was run ↓Read the study →
- models
- 12
- of members opened a section
- 55%
- for the most opened section
- 4.9%
- for the whole run
- ~$50
Live Preferences · Price against picks
LIVE PREFERENCES · HERO · NOV 2, 2026Cost of the run on the bottom, head to head up the side. Hover a model for its 95% interval.128K ran into the 128k reasoning cap
Live Preferences leaderboard · Twelve models, four briefs each
LIVE PREFERENCES · HERO · NOV 2, 2026| Model (12) | ||||||
|---|---|---|---|---|---|---|
| 1 | GPT-6 Astra | $8.09 | 17 min | |||
| 2 | GPT-6.1 Sol | $1.50 | 14 min | |||
| 3 | Grok 4.7 | $2.41 | 22 min | |||
| 4 | Claude Sonnet 5.5128K | $1.71 | 6 min | |||
| 5 | Claude Fable 5.1128K | $15.96 | 17 min | |||
| 6 | Muse Spark 1.3 | $0.41 | 2 min | |||
| 7 | Gemini 3.8 Flash$ | $0.22 | 1.5 min | |||
| 8 | Claude Opus 5.5128K | $5.71 | 11 min | |||
| 9 | Qwen 3.8 Max | $1.38 | 7 min | |||
| 10 | GLM 5.3 | $1.21 | 9 min | |||
| 11 | MiMo v2.6 Pro | $0.10 | 10 min | |||
| 12 | Kimi K3 | $1.39 | 9 min |


Two ways to rank · Pick rate on the left, head to head on the right
LIVE PREFERENCES · HERO · NOV 2, 2026By pick rate
Head to head
- 1GPT-6 Astra
- 2GPT-6.1 Sol
- 3Grok 4.7
- 4Claude Sonnet 5.5
- 5Claude Fable 5.1
- 6Muse Spark 1.3
- 7Gemini 3.8 Flash
- 8Claude Opus 5.5
- 9Qwen 3.8 Max
- 10GLM 5.3
- 11MiMo v2.6 Pro
- 12Kimi K3
- 1GPT-6.1 Sol
- 2GPT-6 Astra
- 3Gemini 3.8 Flash
- 4Claude Sonnet 5.5
- 5Claude Fable 5.1
- 6Muse Spark 1.3
- 7Qwen 3.8 Max
- 8Grok 4.7
- 9GLM 5.3
- 10Claude Opus 5.5
- 11MiMo v2.6 Pro
- 12Kimi K3
The rankings agree at both ends: the two GPT models are first and second on both, and Kimi K3 is last on both. They disagree most about Grok 4.7, third by pick rate and eighth head to head, and Gemini 3.8 Flash, seventh by pick rate and third head to head.
Take rate · Who opened a section, and who took its prompt
LIVE PREFERENCES · HERO · NOV 2, 2026- 1Claude Opus 5.57 of 6710%
- 2Gemini 3.8 Flash8 of 7810%
- 3Claude Sonnet 5.56 of 827%
- 4GPT-6.1 Sol7 of 1027%
- 5Muse Spark 1.35 of 816%
- 6GPT-6 Astra6 of 1105%
- 7GLM 5.33 of 615%
- 8Claude Fable 5.13 of 794%
- 9Grok 4.73 of 873%
- 10Qwen 3.8 Max2 of 643%
- 11Kimi K31 of 353%
- 12MiMo v2.6 Pro1 of 552%
52 of the 901 members who opened a section took its prompt (5.8%), every one of them after opening it. Some sections get looked at and left: Grok 4.7 is third by pick rate and near the bottom here. Too few copies to rank on yet: the twelve take rates can't be told apart (p ≈ 0.47).
What the 52 prompts were built for
- Extended prompt 41
- Claude Code 9
- Cursor 1
- Codex 1
Results
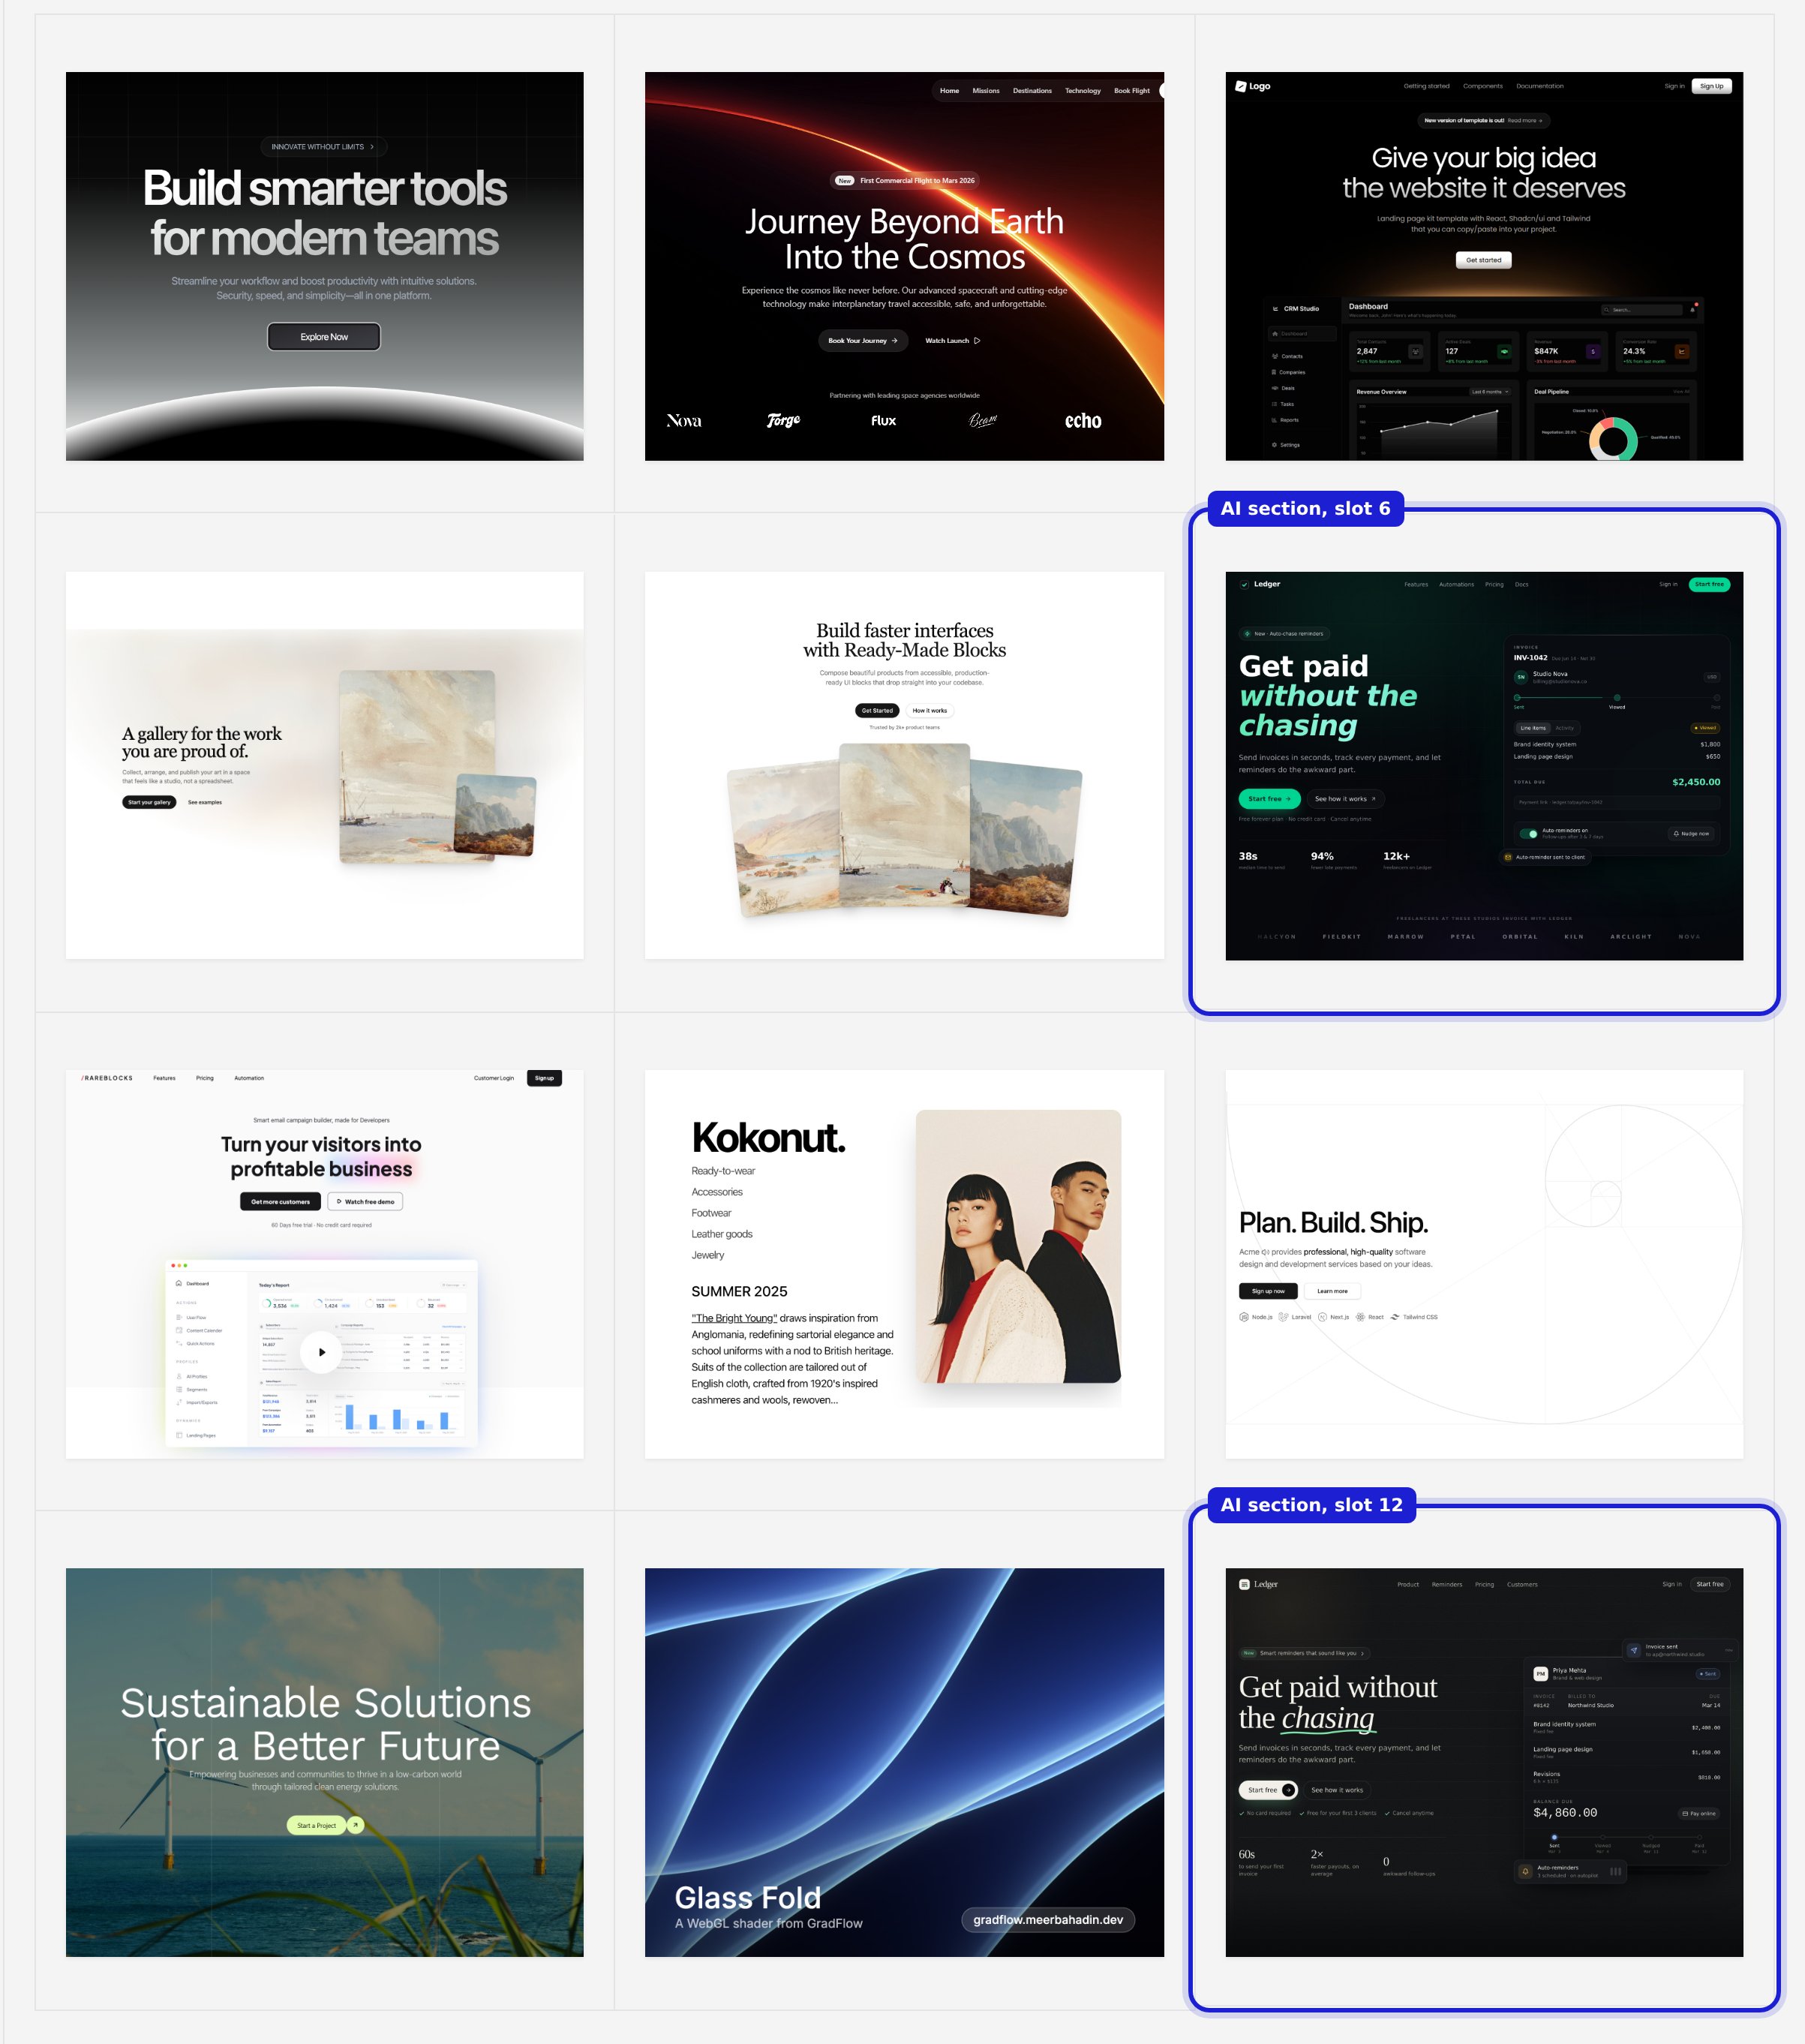
AI-made sections hold up against human-made cards. In the same feed slot they get opened about as often, and the share of visitors who open anything at all is 55% with the AI sections and 52% without them.
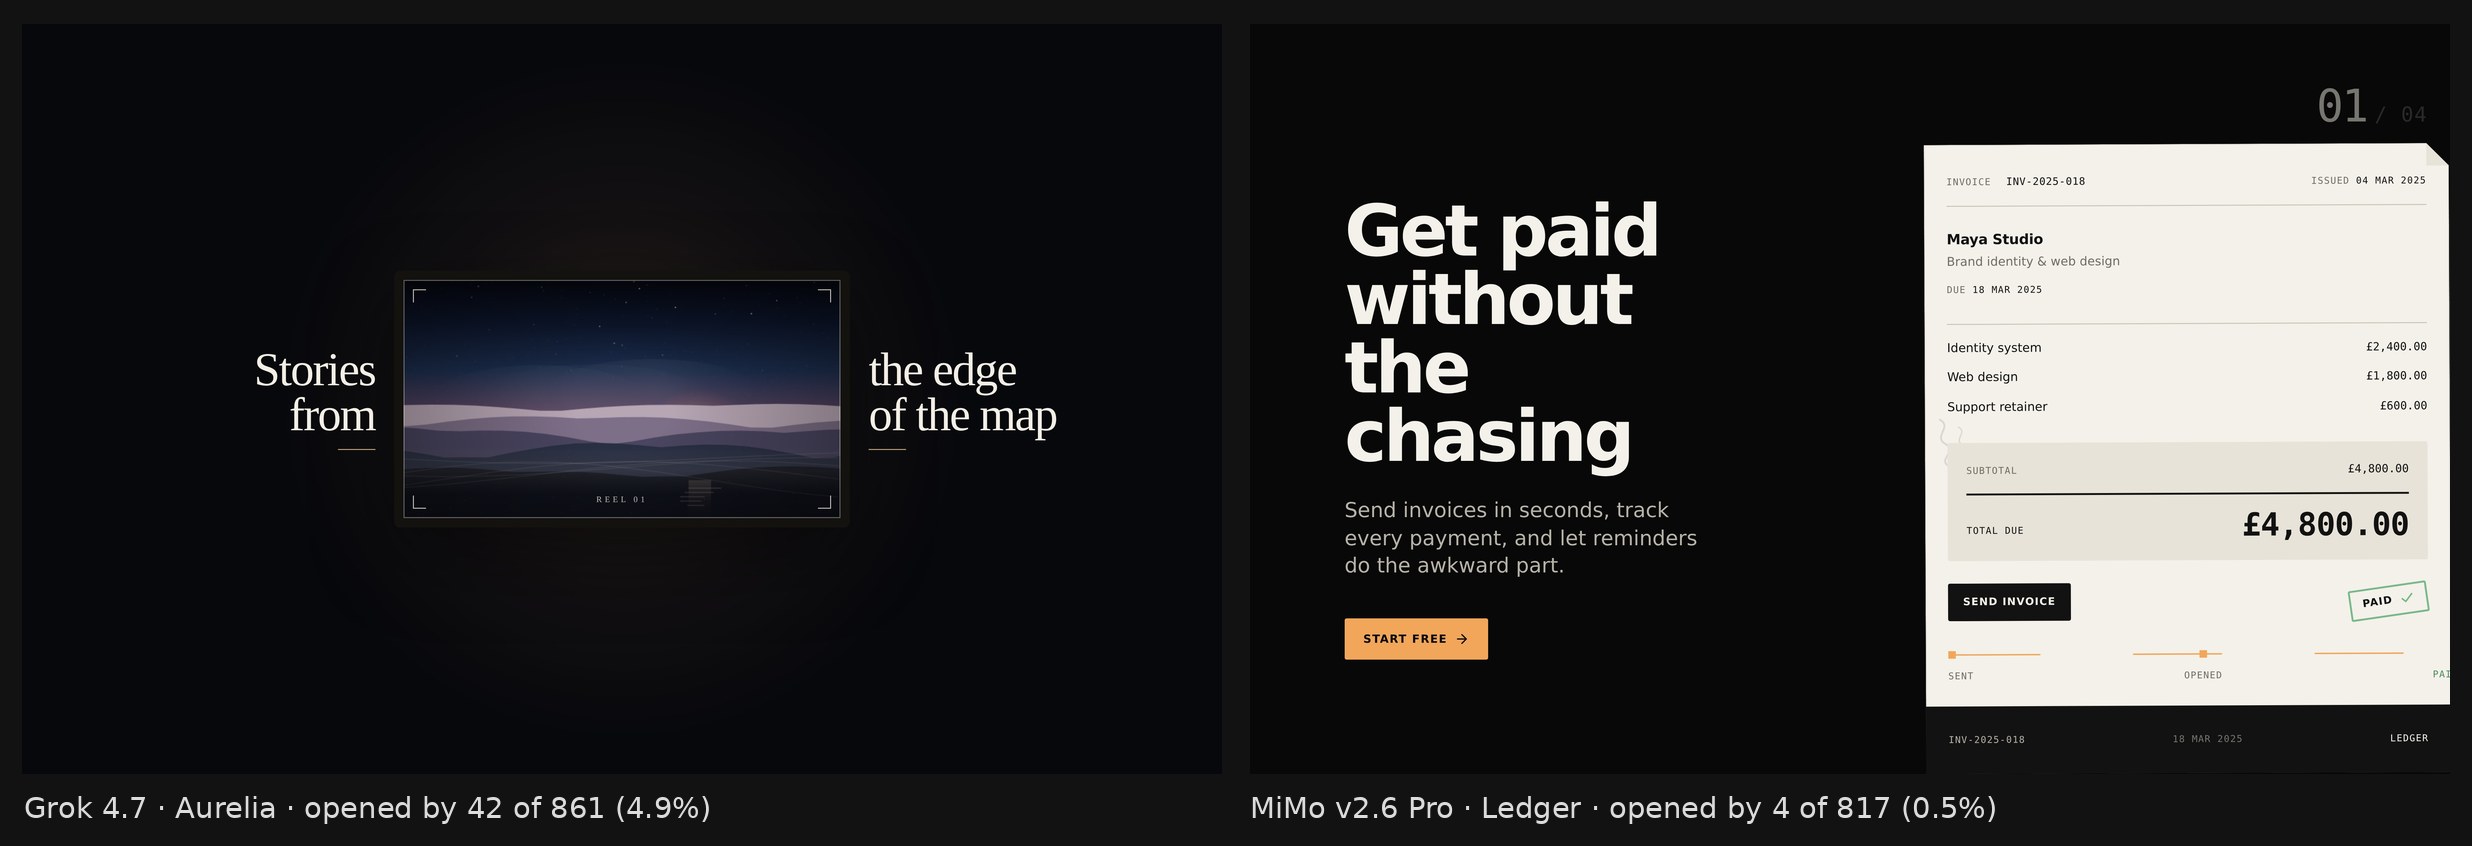
The models do differ overall (p < 0.001 across all models), but no single leader is ahead of the rest beyond the margin of error. The brief made a difference too, though a smaller one than the slot: Aurelia, where the models' designs differed the most, led the other briefs (p ≈ 0.003).
AI section vs human card, same slot
Slot 6
- AI section548 / 14,3253.8%
- Human card49 / 1,5803.1%
Slot 12
- AI section319 / 11,7792.7%
- Human card25 / 8822.8%
Open rate by brief
- Ledger188 / 9,6931.9%
- Orbit246 / 10,0162.5%
- Aurelia268 / 10,0732.7%
- Nocturne202 / 10,0052.0%
What developers saw
The 48 sections were published from one neutral account with matching covers, and the cards don't show the model. Signed-in visitors to the hero page see two of them in the feed, at positions 6 and 12, from the same brief and two different models.
How it was run
The models and the prompt
12 models, each at its highest reasoning setting that still finished the job, got the same system prompt: two files in the format 21st publishes, React 19 with Tailwind v4, a short list of allowed libraries, no external images, fonts or URLs, and a layout that works from 375 px wide. Each wrote one hero per brief: Ledger, Aurelia, Orbit, Nocturne.
Getting a working component
Every output was rendered in a headless browser at 375 and 1440 px, in light and dark. A model got another attempt only when its first one didn't work. All of them ended up working; one hero cost from $0.02 to $4.53, and the whole run about $50.
The test
Every page view is a blind comparison between two models on one brief. A random 10% of visitors get the normal feed as a control. Pick rate is the share of members who opened a model's section after seeing it, adjusted for the mix of briefs. Head to head uses only views where a member saw both sections and opened exactly one; a Bradley–Terry model turns the duels into ratings on the Elo scale and takes out the advantage of slot 6. Take rate is the share of members who opened a section and then pressed Copy prompt on it.