Category “FAQ”
No model picked A: 8 of 11 picked B and 3 couldn't decide. Opus called B "the practical, readable pattern most developers drop into a real product".
Can a model tell which of two components developers will copy into their project? The best, Claude Opus 5.5, agrees with developers 77% of the time, then Claude Sonnet 5.5 at 72%. A coin gets 50%
How often each model picks the component developers prefer
Share of pairs of 21st components, each asked in both orders. Guessing at random gets 50%
a coin, 50%. The weak control, Gemma 3 4B, lands right on it
01
When both components are plain and developers strongly prefer one, nearly every model picks it too
02
Where developers go for gradients, glow or 3D, the models stay with the plain, safe option. A judge built on today's models would underrate the components developers actually want
03
Models point at bugs, cramped layouts and placeholders, yet developers sometimes pick that component anyway, likely because they will rework it in their own project
04
Live frames, video, source code and 40 solved examples barely moved the scores. The gap is in what the models prefer, not in what they see
05
Prompting won't teach a model this taste. Training on what developers actually pick might, and 21st records such choices every day
The pairs from the study, sorted by how the models did. The blue frame marks the component developers copied more
More models picked the other component than the developers' choice. A few examples from the group
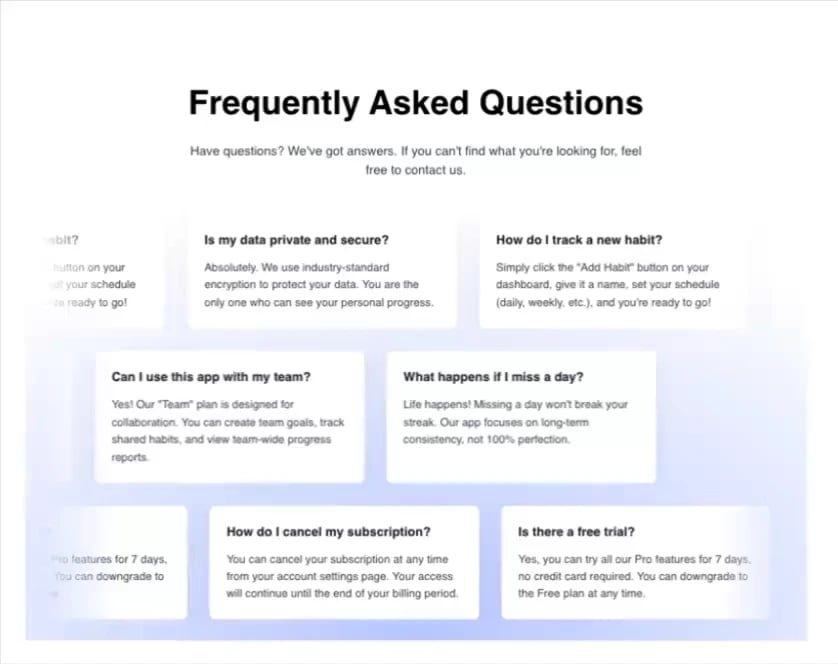
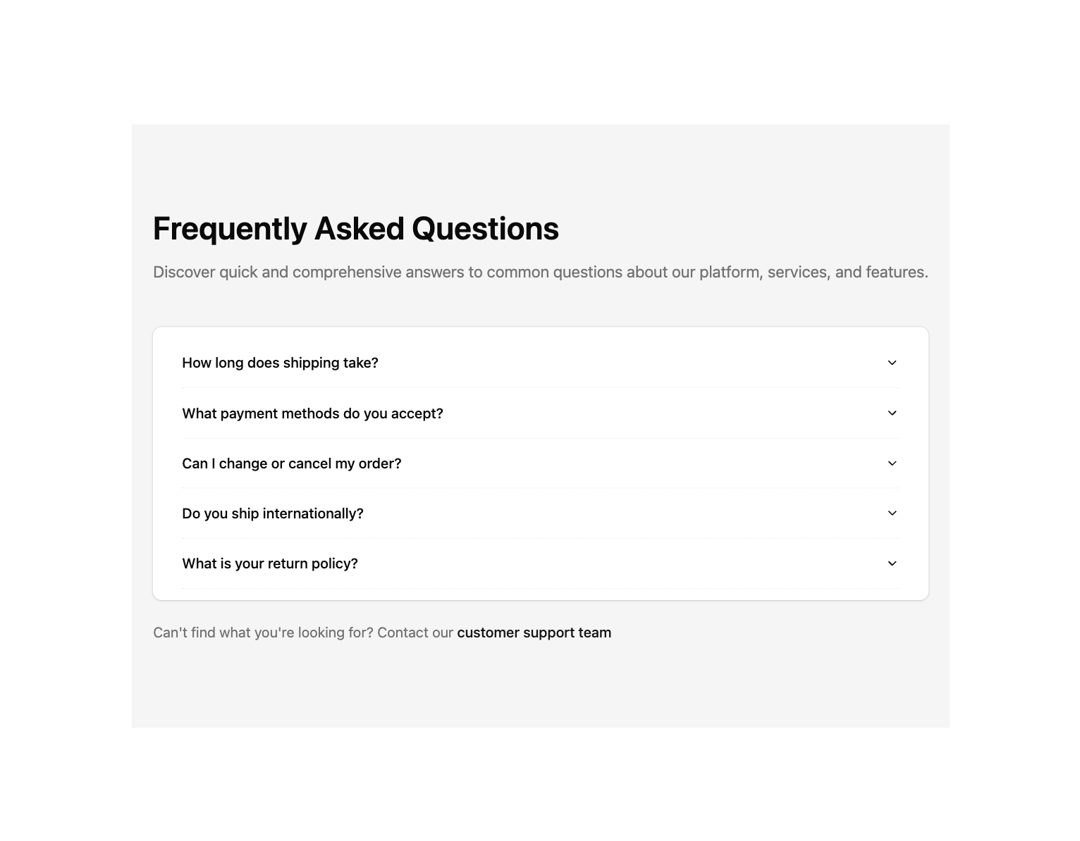
Category “FAQ”
No model picked A: 8 of 11 picked B and 3 couldn't decide. Opus called B "the practical, readable pattern most developers drop into a real product".
Category “Pricing”
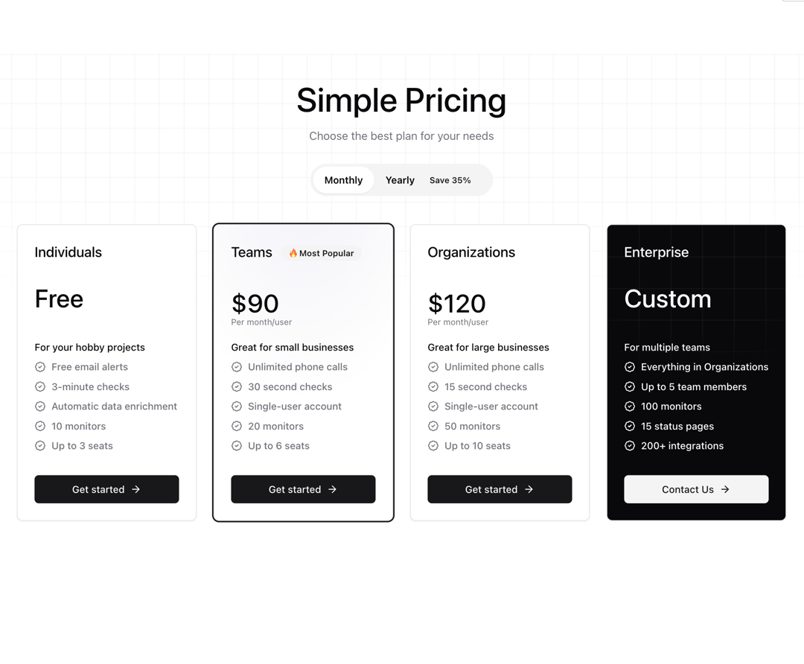
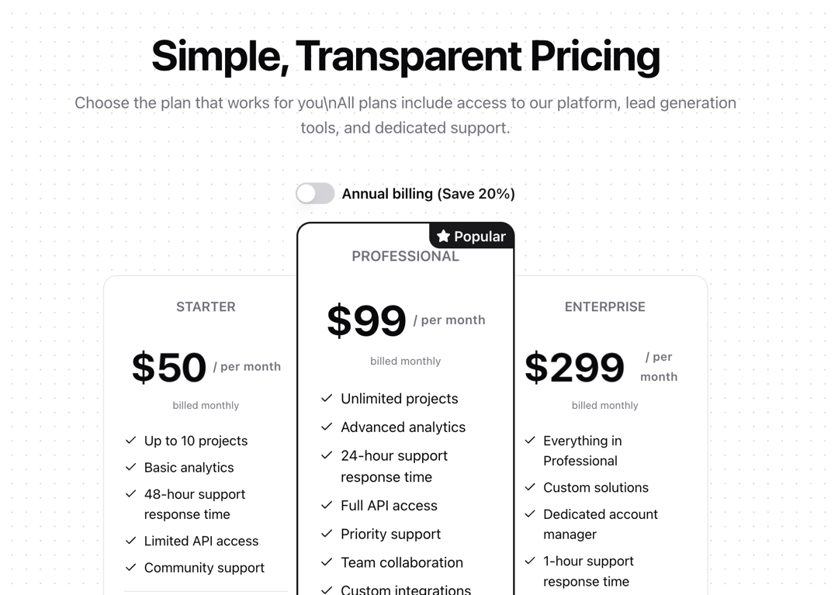
No model picked B, 9 picked A, and Opus and Fable couldn't decide. Sonnet pointed at B's "visible '\\n' text bug in its subtitle, a cropped preview and cramped cards". Developers copied it more anyway.
Search “reviews”
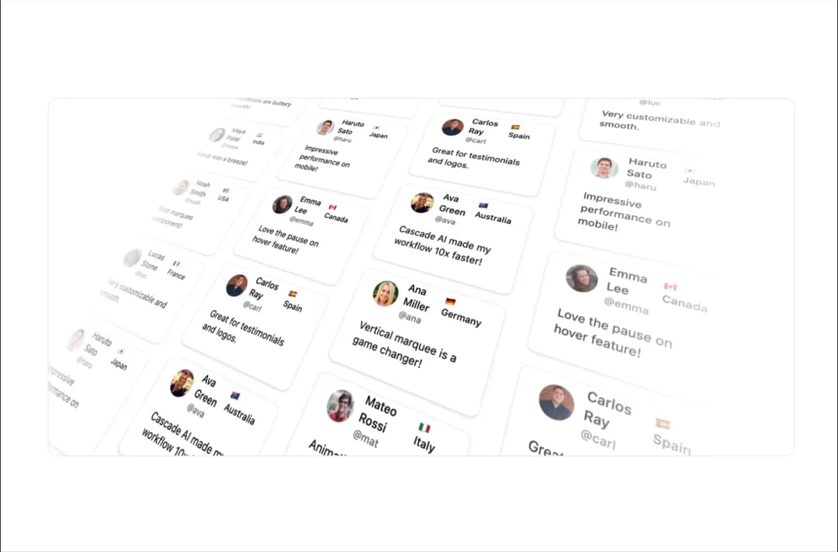
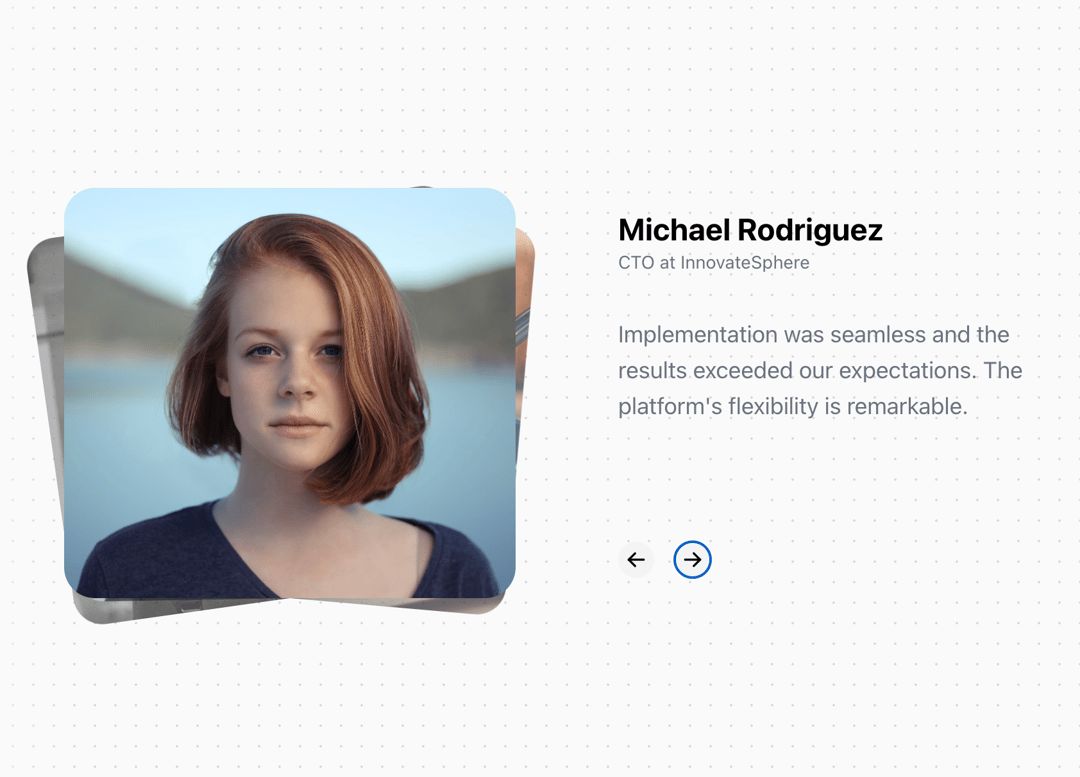
No model picked A, 6 picked B and 5 couldn't decide.
Search “hero”
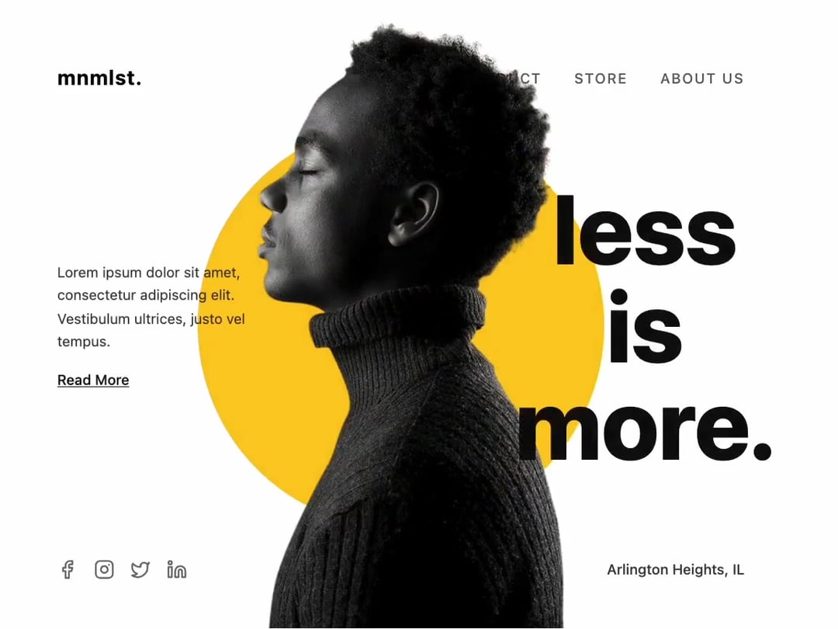
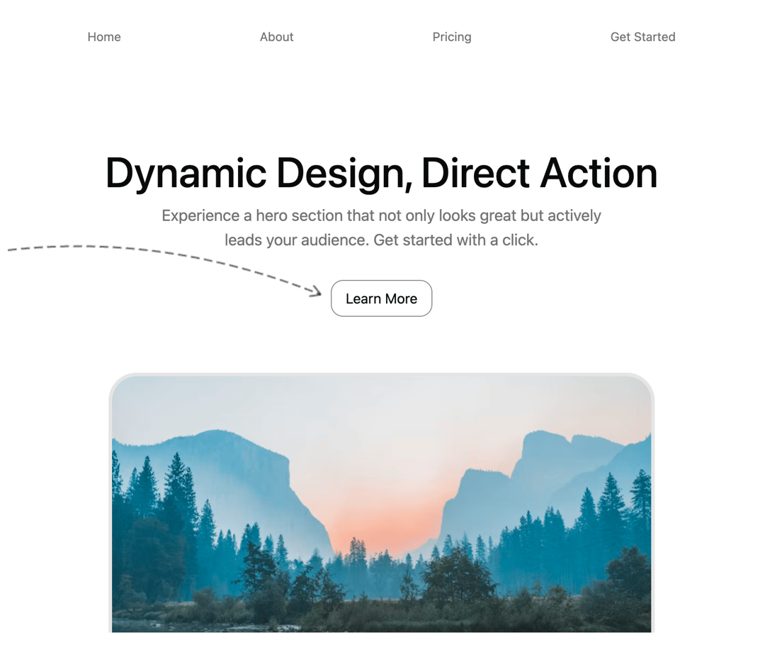
1 of 11 models picked A, 7 picked B and 3 couldn't decide. Opus, the only model that picked A, said it "stands out on the results page and feels premium".
Search “card”
1 of 11 models picked B, 7 picked A and 3 couldn't decide.
Category “3D Gallery”
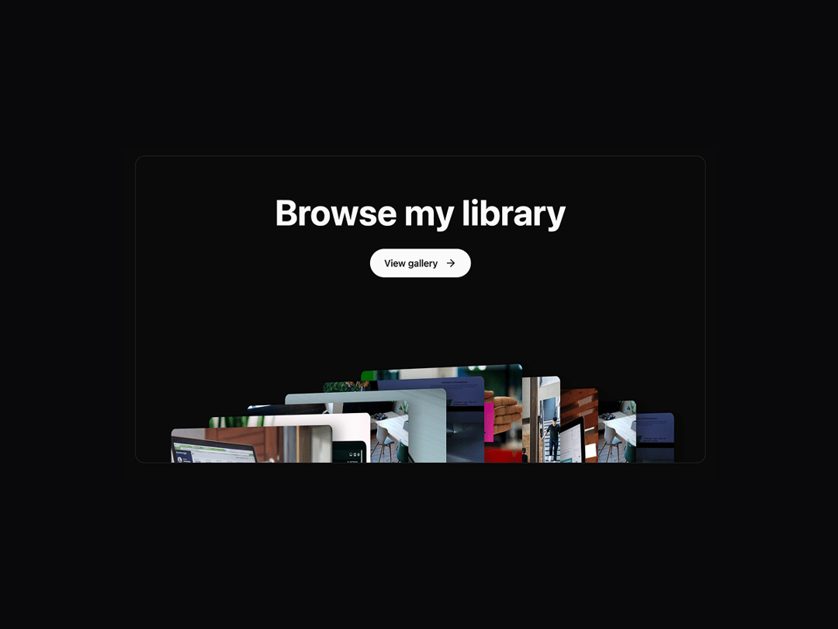
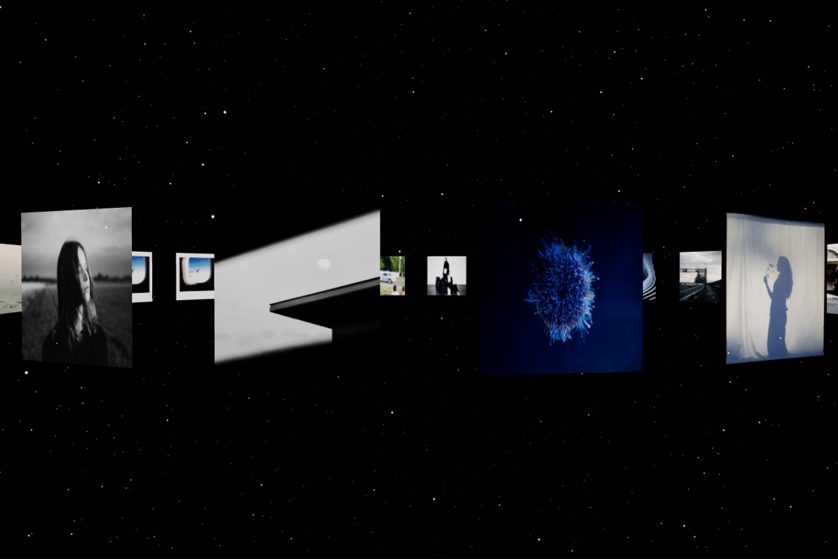
2 of 11 models picked B, 5 picked A and 4 couldn't decide. Grok, which picked B, said developers in this category copy "the component whose preview is unmistakably a dramatic orbiting gallery".
Category “Features”
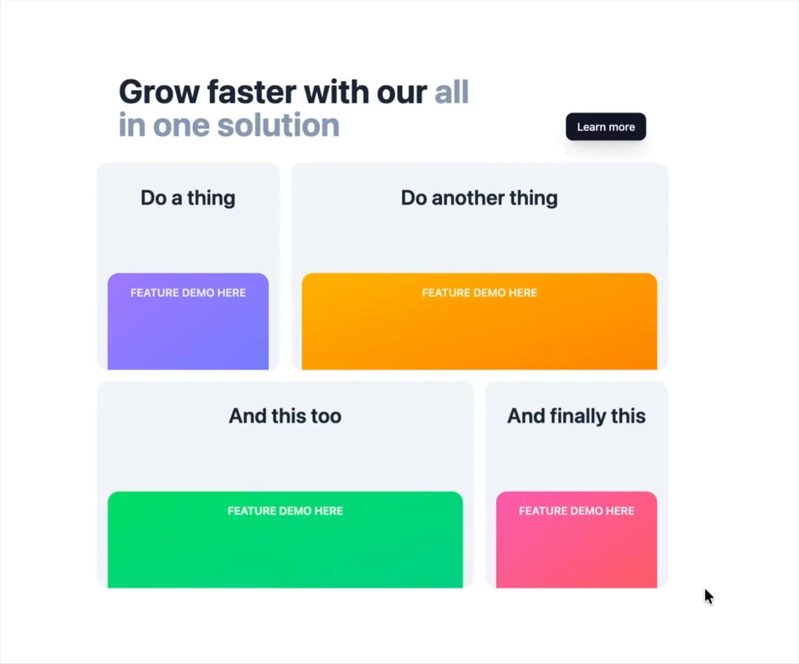
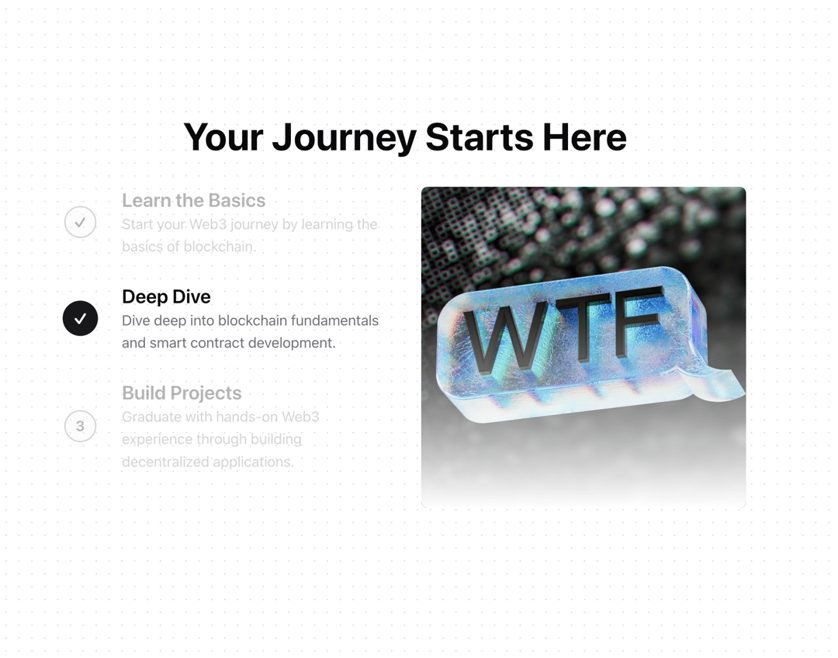
2 of 11 models picked B, 8 picked A and Fable couldn't decide. Opus, which picked B, noticed that A's grid shows only "'FEATURE DEMO HERE' placeholders that leave most of the real work to the developer".
Category “Data Visualization”
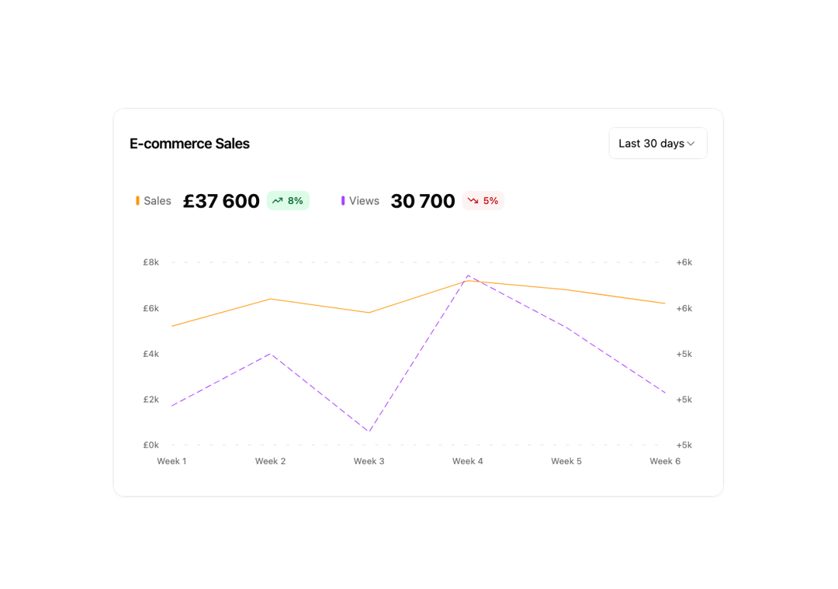
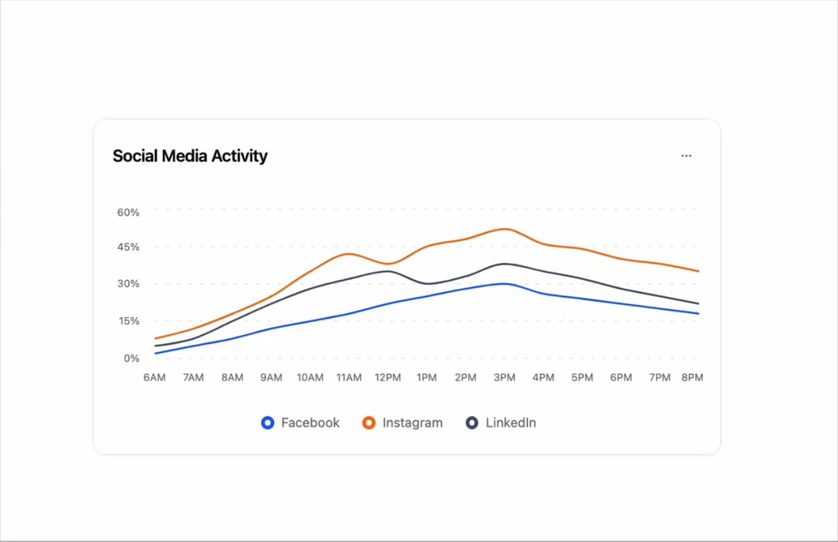
2 of 11 models picked B, 5 picked A and 4 couldn't decide. Grok, which picked B, said A's "duplicated secondary-axis labels look broken".
The same final prompt, with more for the models to look at. None of the three changes moves them beyond noise
| Model | One screenshot | + frames, video, description | + source code | Screenshot + 40 examples |
|---|---|---|---|---|
| Claude Opus 5.5 | 77% | 78%+1 | 78%+1 | 72%−5 |
| Claude Sonnet 5.5 | 72% | 73%+1 | 71%−1 | 73%+1 |
| GPT-6 Astra | 72% | 74%+2 | 72%±0 | 73%+1 |
| GPT-6.1 Sol | 71% | 67%−4 | 71%±0 | 72%+1 |
| Claude Fable 5.1 | 71% | 73%+2 | 70%−1 | 73%+2 |
| Gemini 4 Argon | 69% | 72%+3 | 72%+3 | 70%+1 |
| Muse Spark 1.3 | 67% | 74%+7 | 66%−1 | 66%−1 |
| Kimi K3.1 Pro | 66% | 71%+5 | 69%+3 | 69%+3 |
| Qwen 3.8 Max | 63% | 62%−1 | 66%+3 | 65%+2 |
| MiMo v2.6 Pro | 62% | 63%+1 | 59%−3 | 60%−2 |
| Grok 4.7 | 62% | 73%+11 | 63%+1 | 68%+6 |
| Gemma 3 4B | 50% | 50%±0 | 49%−1 | — |
45 days of searches and category pages on 21st. A copy within 30 minutes of the page counts as a pick, corrected for the position on the page. Then only pairs where nothing but the components can explain the gap
The picks are stable
Split the users into two random halves and the same component wins in 98% of pairs in both. Paying subscribers alone agree with everyone in 95–97%
Limits
Only large gaps of 3 times or more, from frequent searches and category pages. This is the taste of developers picking ready-made components on 21st, and it may not carry over to designers or end users
The pairs, a held-out set for evals, and the choices developers make on 21st every day
Request the pairs